GEMO3DMonocular 3D Vehicle Detection with Deep-Learning Perception, Camera Geometry and Projection-Height Ratio Compensation
TL;DR GEMO3D turns a single RGB image into a 3D vehicle box by correcting pinhole depth with a class-specific rank-1 projection-height ratio model.
165 matched vehicle instances in CARLA evaluated by all four methods · next best: MonoDETR.
Abstract
Monocular 3D vehicle detection must infer depth from a single image. The height of a detected 2D box follows the visible silhouette, so it differs from the projected height of the vehicle’s 3D centerline — a bias that changes with viewing angle, distance and vehicle shape. GEMO3D combines deep-learning-based vehicle detection, vehicle-type classification and observation-angle estimation with camera geometry, and corrects this bias using a vehicle-type-conditioned rank-1 projection-height ratio model estimated from the viewing angle and initial pinhole depth. The corrected depth is back-projected into 3D, with the bottom-center position constrained by the road plane. The 3D bounding box is then reconstructed and further refined through reprojection consistency, without requiring ground-truth depth at inference.
Method
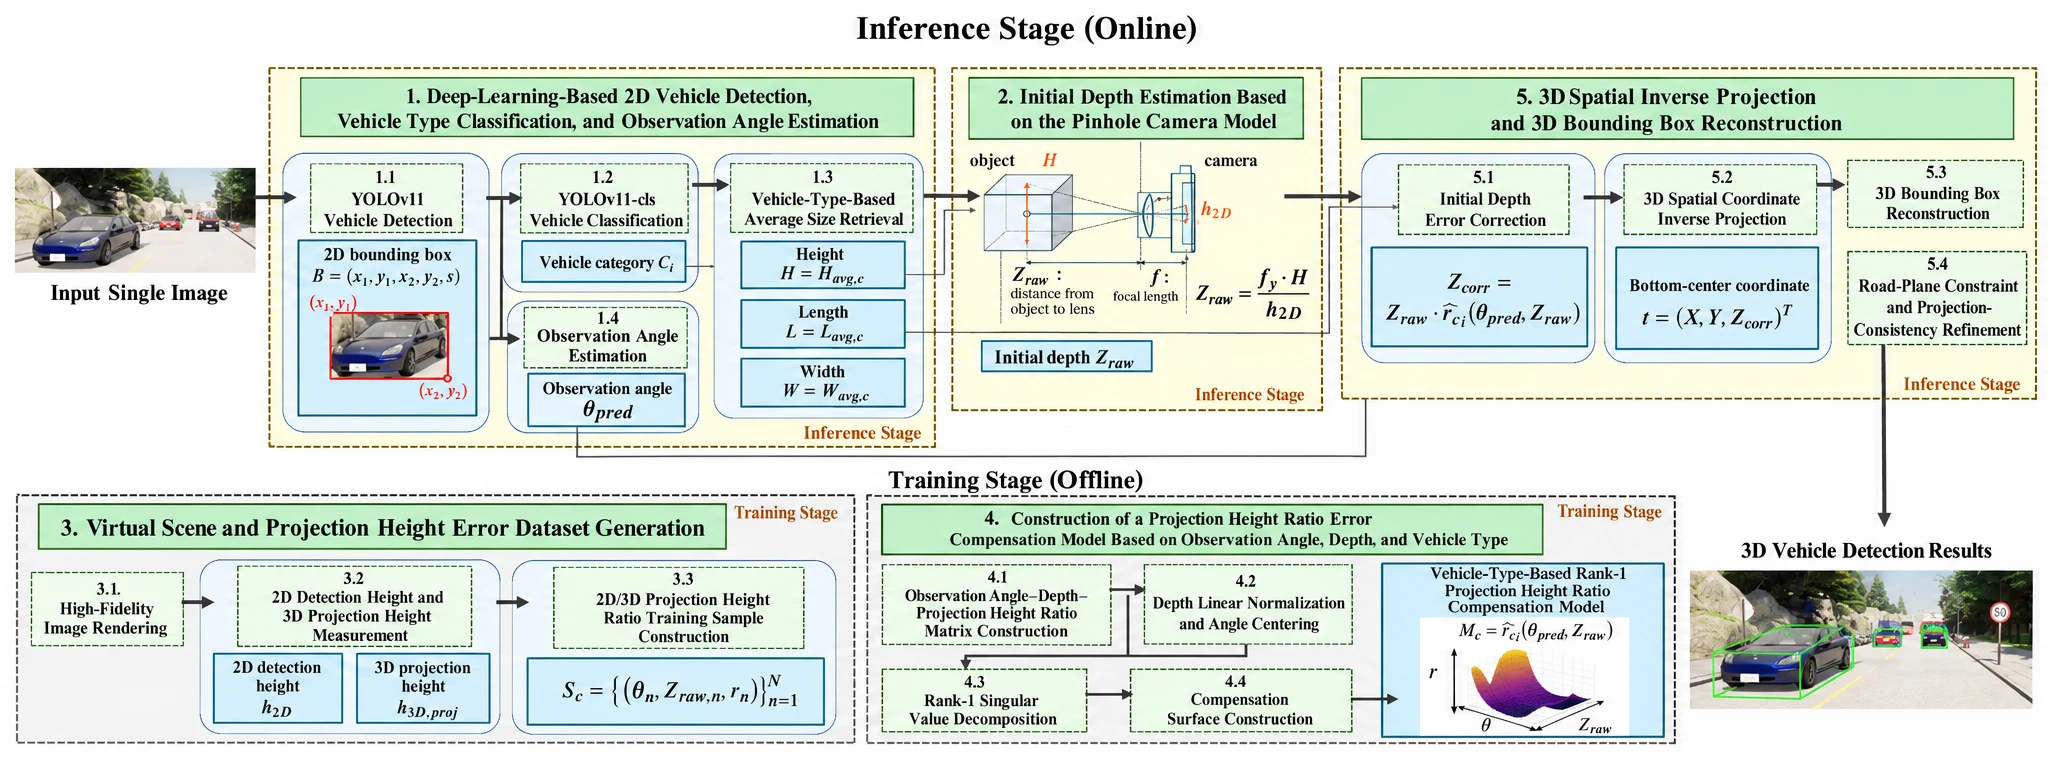
Core contribution
Rank-1 Projection-Height Ratio Model
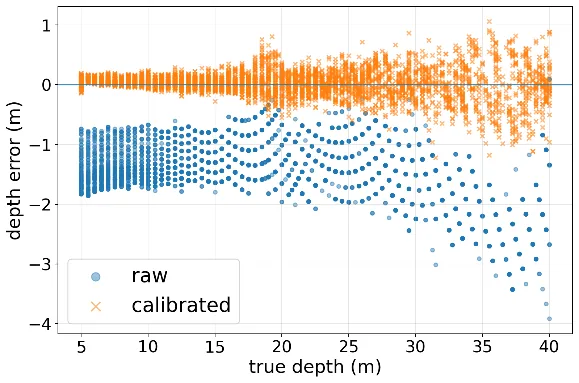
A 2D box follows the silhouette, so its height differs from the projected 3D centerline by a ratio r = h2D / h3D,proj that varies with viewing angle and depth. GEMO3D learns this ratio surface per vehicle class and compresses it with a rank-1 SVD.
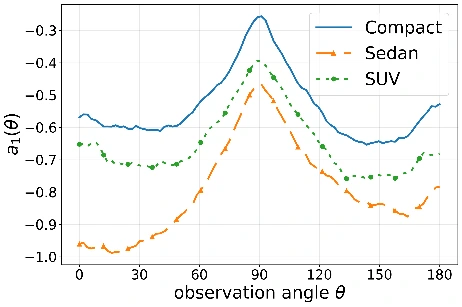
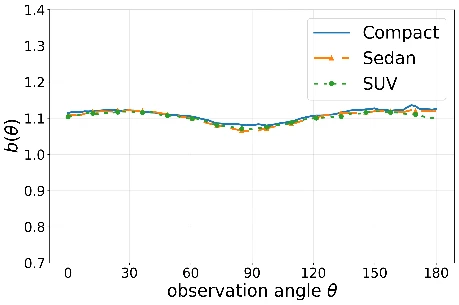
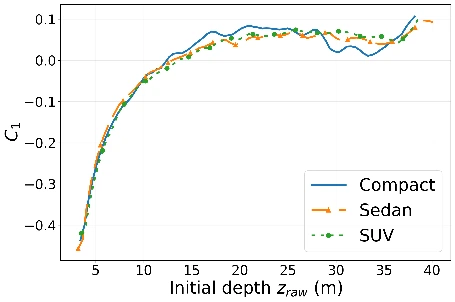
Compact 95.11 · Sedan 98.55 · SUV 98.94
Blender renders · no real-road 3D labels
Results
165 matched vehicle instances in a CARLA sequence, detected by GEMO3D, MonoAMNet, MonoDGP and MonoDETR.
| Method | Mean depth bias (m) → 0 | Depth RMSE (m) ↓ | Yaw error (°) ↓ | 3D center error (m) ↓ | BEV IoU ↑ | FPS ↑ |
|---|---|---|---|---|---|---|
| MonoAMNet | −2.29 | 5.58 | 18.97 | 2.76 | 0.46 | 40.23 |
| MonoDGP | −1.22 | 1.40 | 1.23 | 1.25 | 0.46 | 24.71 |
| MonoDETR | −0.02 | 0.33 | 1.73 | 0.28 | 0.70 | 21.34 |
| GEMO3D ours | −0.06 | 0.27 | 2.12 | 0.25 | 0.82 | 31.12 |
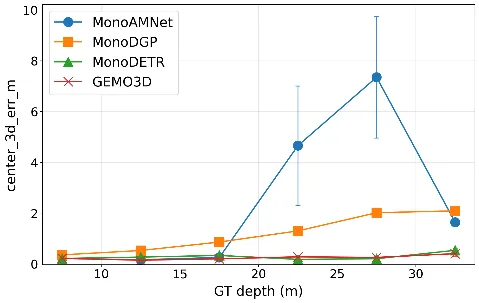
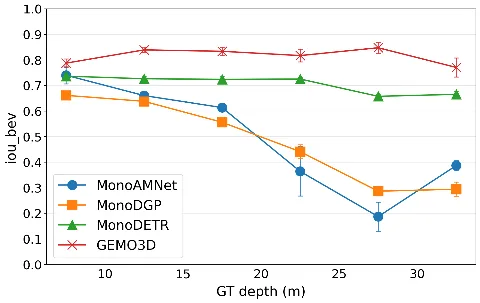
Center-error and BEV IoU plots: mean per 5 m ground-truth depth bin (5–35 m); error bars show the 95% confidence interval.
2D detection → 3D box
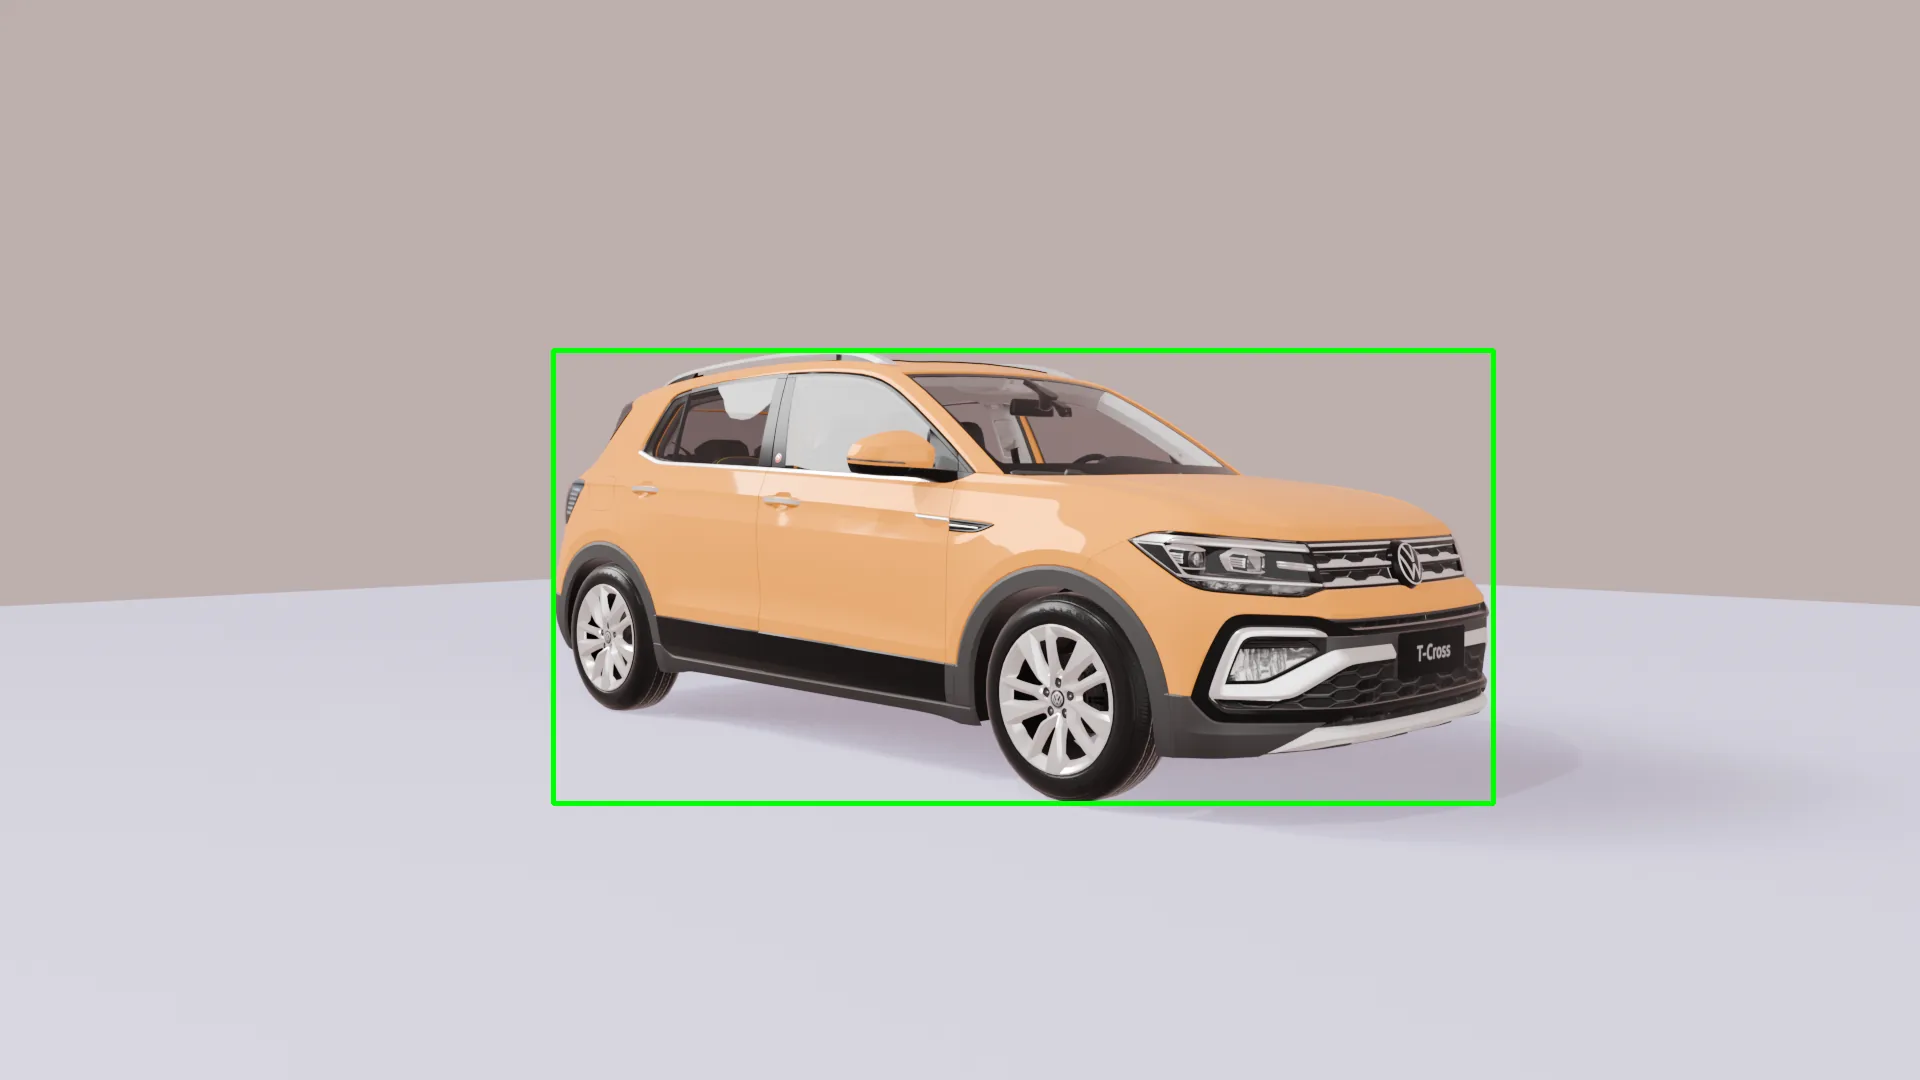 3D box2D detection
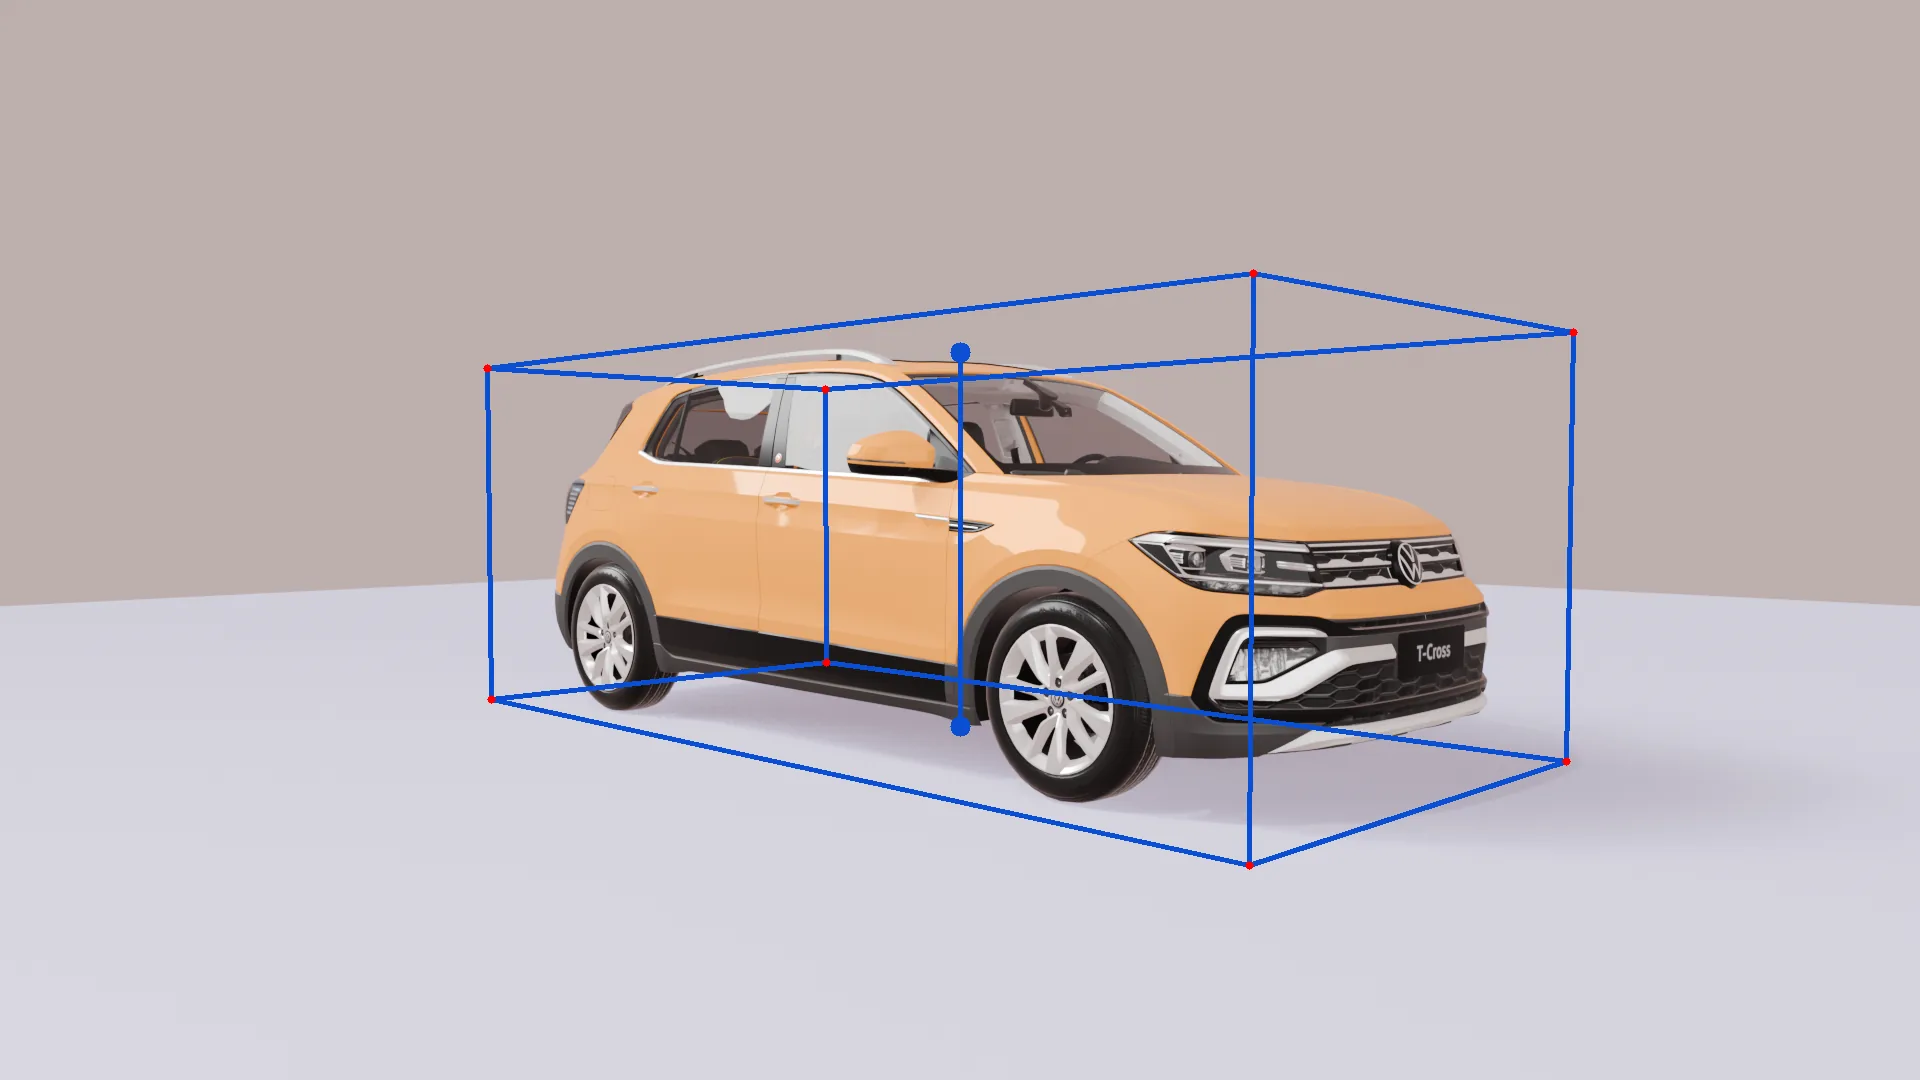
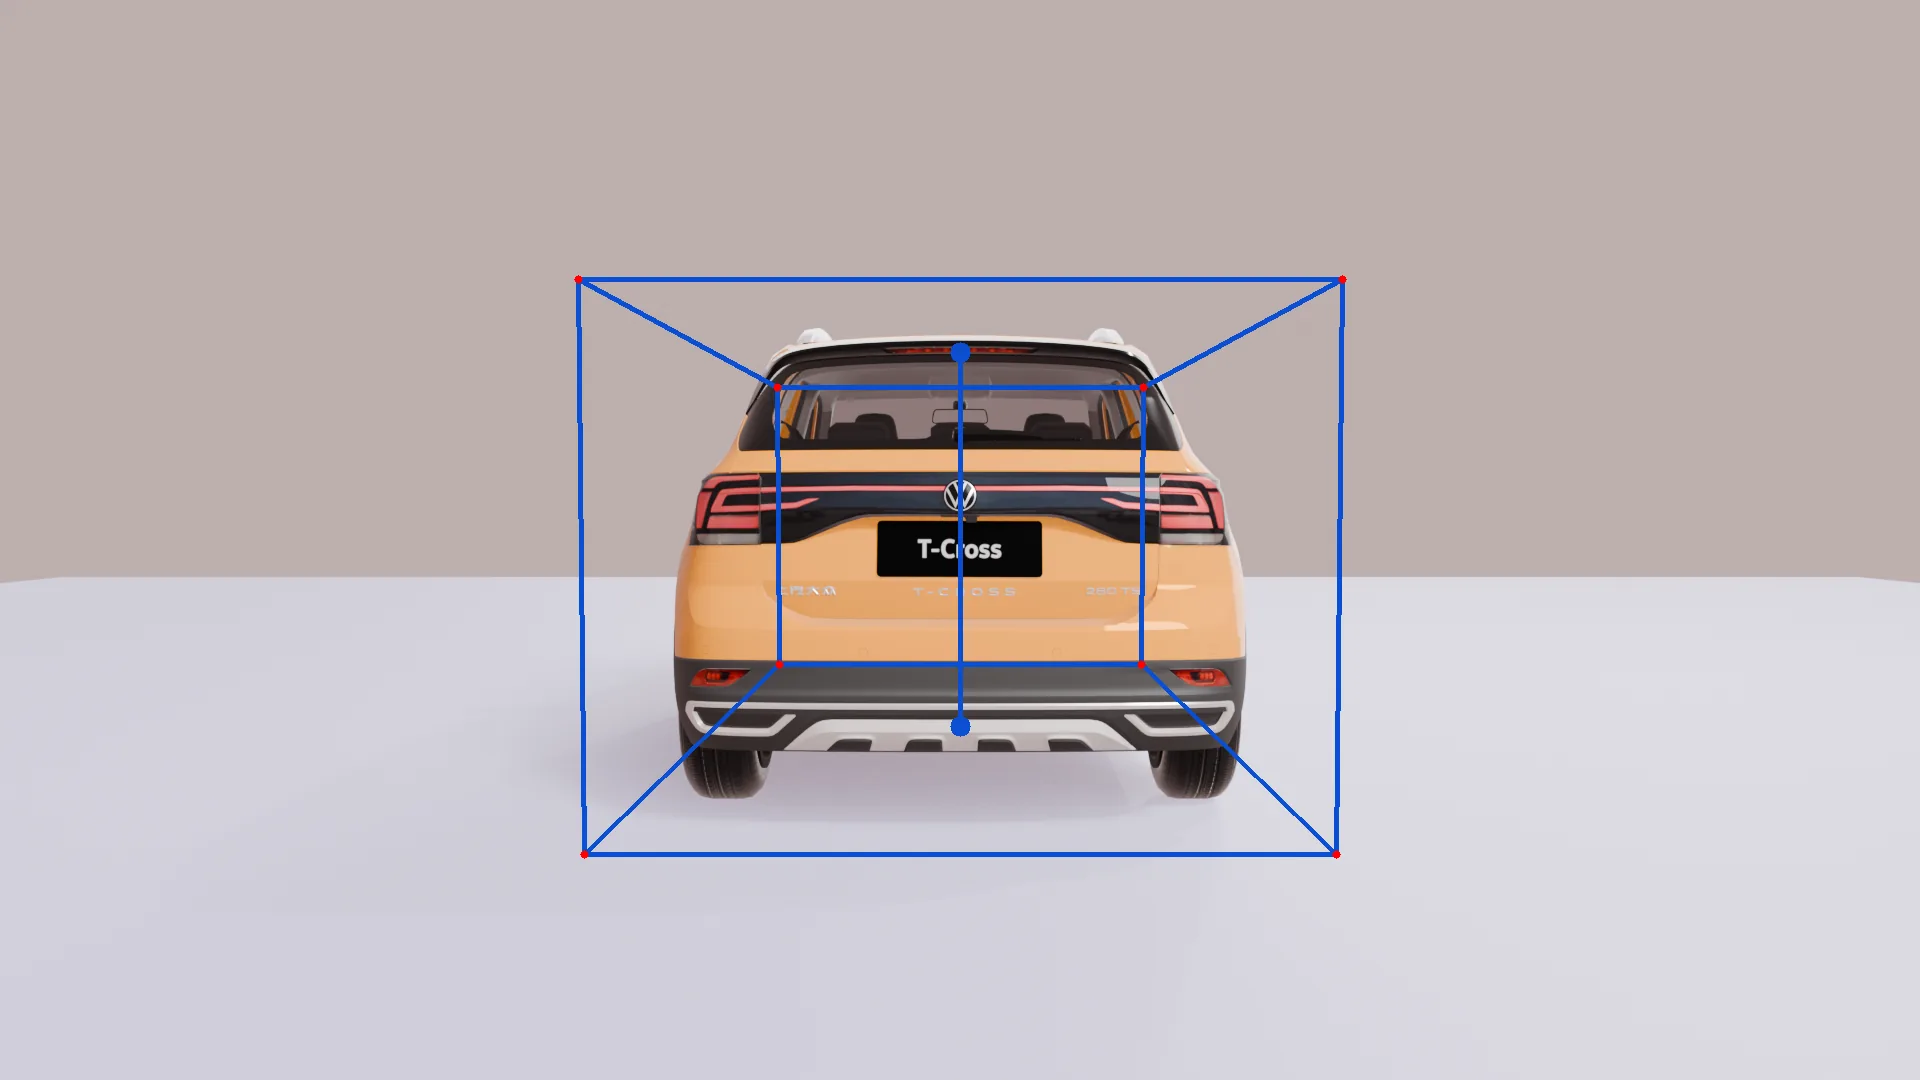
Predictions at 10, 20 and 30 m
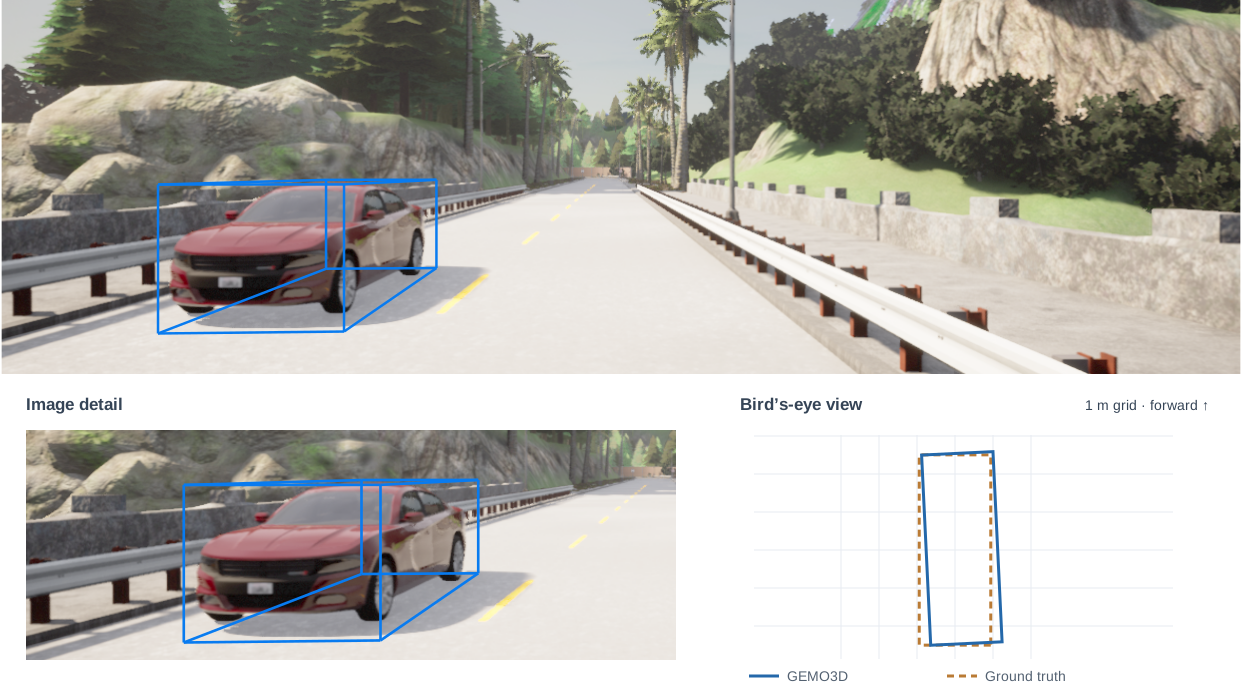
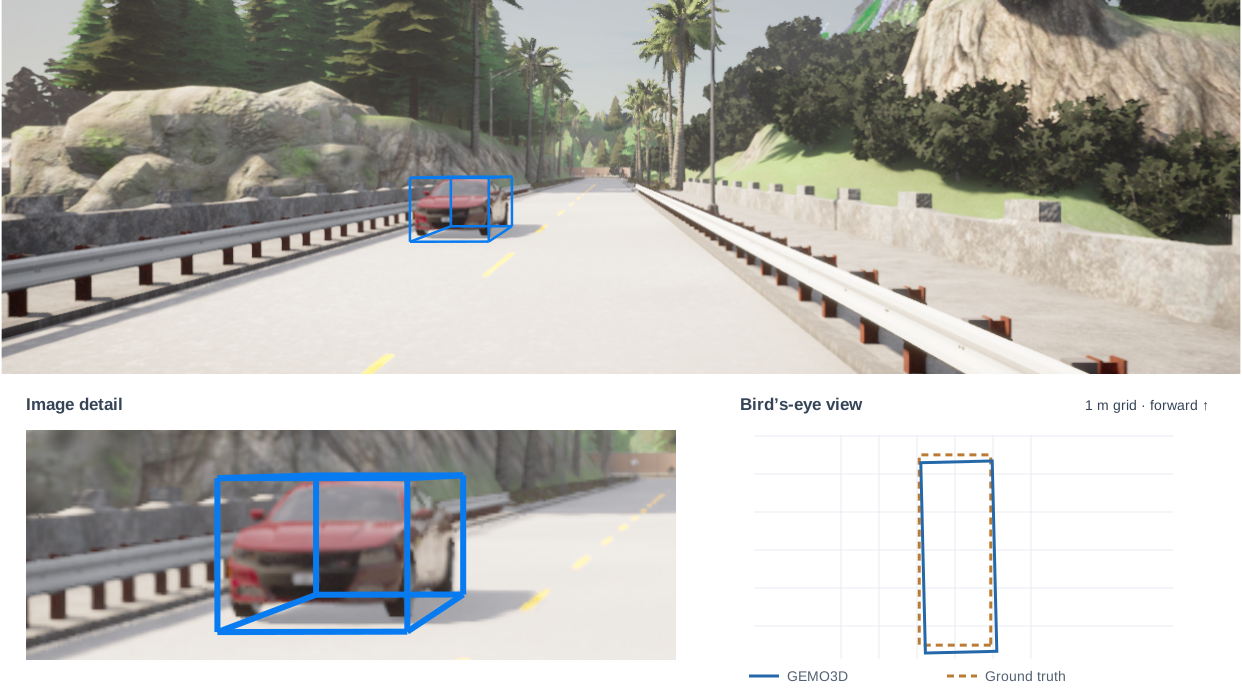
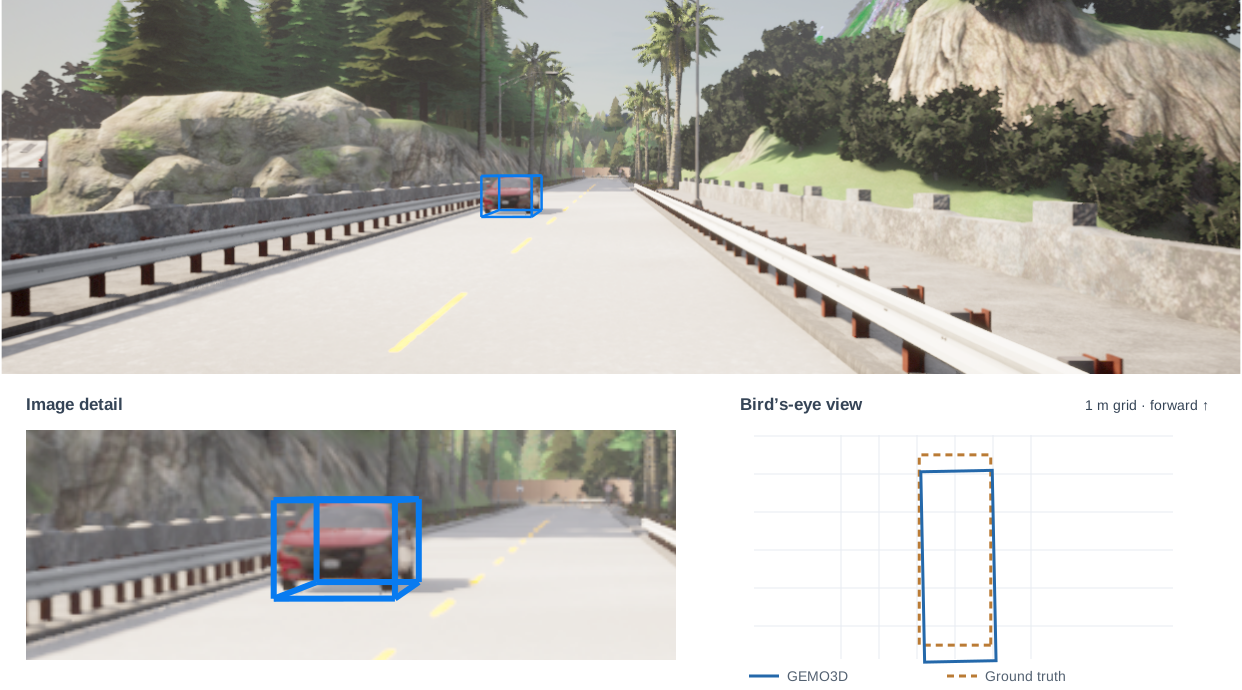
Blue: GEMO3D. Bird’s-eye view: orange dashed ground truth, 1 m grid. Examples are representative frames from the evaluation sequence.
Limitations. Evaluation covers a CARLA bidirectional-road scenario. Results depend on 2D box quality: severe occlusion, truncation or very small distant boxes can amplify depth errors, and vehicle-type misclassification propagates to the size prior and the ratio model. Future work will extend the model to more vehicle types, camera heights, pitch angles and road slopes.
BibTeX
@misc{chang2026gemo3d,
  title={GEMO3D: Monocular 3D Vehicle Detection with Deep-Learning Perception, Camera Geometry and Projection-Height Ratio Compensation},
  author={Chang, Yu-Chiao and Kuo, Chunghui and Yang, Chieh-Lun and Chang, Ing-Chau},
  year={2026},
  note={CVGIP 2026, SS09-08}
}